
A new account reaches the job queue before it reaches the rest of the database.
That sounds impossible the first time you see it. The account has an ID. The request log contains a successful INSERT. Yet a worker starting at almost the same moment raises ActiveRecord::RecordNotFound, and retrying the job a second later usually works.
Callbacks let an application react to persistence without putting every consequence in a controller or service object:
before_validation
after_validation
before_save
after_save
after_commit
Read from top to bottom, this looks like one lifecycle with after_commit at the far end. For a save that opens and closes its own transaction, that picture is close enough. It breaks down when the save joins a larger operation.
Signup is a good example. It may begin as one Account.create!, then grow to create an entitlement, record an audit event, claim an invitation, and arrange work for another process. The application wraps those writes in a transaction because they should become durable together.
The model may still carry a callback written when account creation was the whole operation:
class Account < ApplicationRecord
  after_save :enqueue_sync

  private

  def enqueue_sync
    AccountSyncJob.perform_async(id)
  end
end
It has probably worked for years. Then a fast worker exposes the assumption inside it:
def perform(account_id)
  account = Account.find(account_id)
  # ActiveRecord::RecordNotFound
end
The signup transaction supplies the missing part of the story:
Account.transaction do
  account = Account.create!(name: "Acme")
  Entitlement.create!(account:, plan: "growth")
  AuditEvent.create!(account:, action: "account_created")
end
The job can start after the account finishes saving and before signup commits. Two clocks are moving through one operation. The record has finished its save on one connection; the transaction has not finished deciding what every other connection may see.
after_save follows the record clock. after_commit waits for the transaction clock.
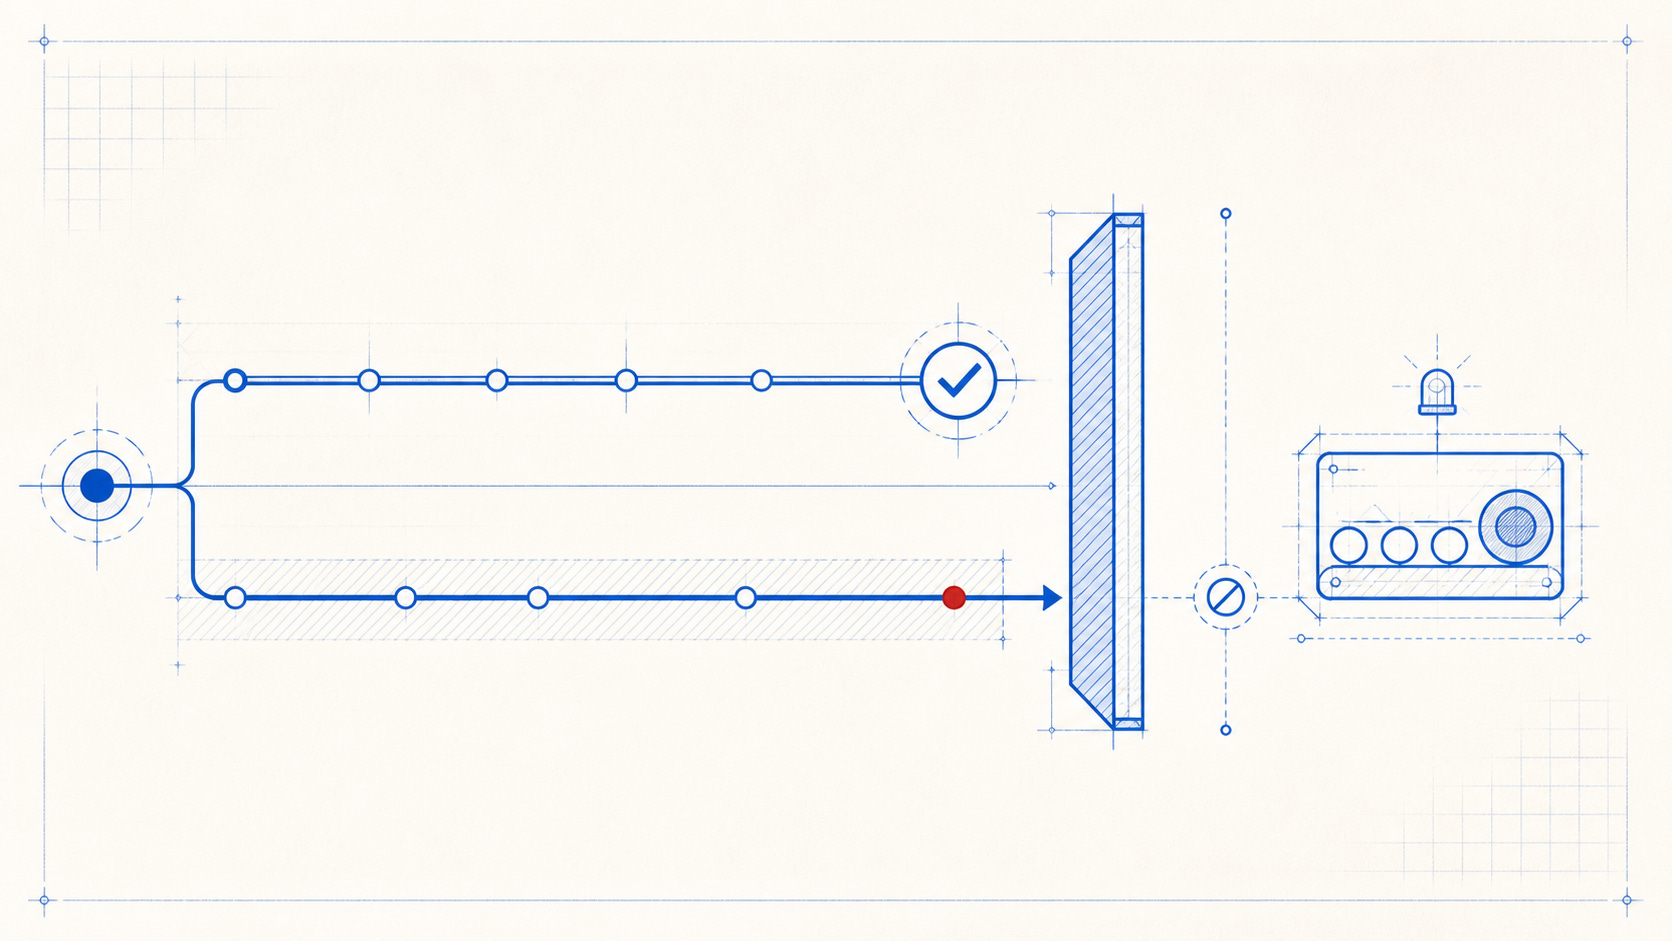
One operation, two clocks
Active Record wraps save and destroy in transactions. If application code already has a transaction open on the same connection, the save joins it. Returning from Account.create! does not insert a commit in the middle of the surrounding block.
The opening failure can therefore happen in this order:
request connection                         worker connection

BEGIN
INSERT accounts
after_save
  push job to Redis  --------------------> receive job
INSERT entitlements                         SELECT accounts WHERE id = 42
INSERT audit_events                         no visible row
COMMIT
The request connection can read its own uncommitted insert. The callback receives an Account with an ID, persisted? returns true, and later SQL in the same transaction can refer to that row.
The worker enters through another connection. Under the usual isolation rules, it cannot see the account until commit. The ID is valid inside the request’s current view of the database and absent from the worker’s.
Queue speed changes how often you notice the mistake. A quiet queue starts the job after commit and makes the code look correct. A busy or unusually fast queue finds the narrow interval before commit.
Retries make this class of bug especially easy to live with. They convert a broken ordering guarantee into a small flake rate, the sort of number a team can watch for years without treating it as a correctness problem. In the common case, the next attempt lands after commit and succeeds. The retry fixed the incident, but it did not fix the handoff.
Then a later write fails:
Account.transaction do
  account = Account.create!(name: "Acme") # job is already queued
  Entitlement.create!(account:, plan: "growth")
  AuditEvent.create!(account:, action: nil) # raises: action must be present
end
Active Record rolls back the account, entitlement, and audit writes. Redis does not participate in that transaction. The worker now holds the ID of an account that will never commit; every retry burns time against an impossible record, and the last attempt can alert someone long after the request that created the problem has disappeared from view.
The same callback produced two incidents. In one, the worker arrived too early. In the other, it was sent toward a state the database rejected. Both begin with the assumption that a successful save has already become durable application truth.
after_save still has useful work to do
after_save runs after the record’s INSERT or UPDATE and before the transaction closes. That position gives it a guarantee that after_commit cannot provide: an exception from the callback can still make the database work roll back.
class Account < ApplicationRecord
  after_save :write_required_ledger_entry

  private

  def write_required_ledger_entry
    LedgerEntry.create!(account: self, event: "account_saved")
  end
end
If the ledger entry must succeed or the account write must fail, keeping both within a single database transaction is useful. The callback and record write share a connection and a rollback path.
There is a condition hidden in that guarantee. The exception must escape the outermost transaction block. If its caller rescues the error inside that block and allows execution to continue, Rails has not performed a partial rollback for the joined save transaction; the outer transaction may still commit. An after_save callback gives you a place inside the rollback boundary, not an exception policy.
Publishing to another process has a different requirement. The worker needs a row visible from its own connection, which the request cannot promise while its transaction remains open.
Choose the callback from the dependency. Use after_save when the extra database work belongs in the write’s rollback path. Use after_commit when another connection must be able to rely on committed state.
The outer transaction decides when commit arrives
Replacing the callback changes the handoff:
class Account < ApplicationRecord
  after_commit :enqueue_sync, on: :create

  private

  def enqueue_sync
    AccountSyncJob.perform_async(id)
  end
end
When Account.create! succeeds, Rails registers the record with the open transaction. The callback does not run when the save method returns. TransactionManager#commit_transaction asks the adapter to commit the database transaction and then runs the registered record and transaction callbacks.1
BEGIN
INSERT accounts
INSERT entitlements
INSERT audit_events
COMMIT
after_commit
  push job to Redis
The worker can now query the committed row through another connection to the primary database. Reading from a lagging replica remains a separate visibility problem; after_commit cannot make replication synchronous.
An inner transaction does not move the callback earlier. When nested work joins the current transaction, there is only one commit to wait for. With a savepoint-backed requires_new: true block, Rails transfers successful records and callbacks to the parent transaction, so a later outer rollback still discards the commit callback.2
This outermost wait is what makes after_commit different from the callbacks surrounding a save. Its macro lives on a model, but its timing belongs to the connection-wide transaction that the model joined.
after_rollback observes the other result. It works for cleanup and diagnostics, which should occur only when database work is rejected. It cannot retract an HTTP request or queue push made earlier. Those effects have already crossed into another system.
One Rails boundary, traced into production
RailsRevelry follows ordinary Rails APIs into framework source and the failures they create in mature systems.
Subscribe free for one source-backed Rails mental model each week.
The workflow may be a better owner than the model
A model callback fits work that should follow every committed occurrence of an event. Deleting a file after a committed record destroy is a familiar example. Signup provisioning is usually narrower.
Accounts may also be created by imports, administrative repair scripts, tests, or data migrations. Putting provisioning in Account#after_create_commit makes all of those paths participate unless they learn how to suppress the callback. The transaction needs to own the timing, but the model does not necessarily need to own the decision.
Rails 7.2 added a transaction object for this case:
def create_account(params)
  Account.transaction do
    account = Account.create!(params)
    Entitlement.create!(account:, plan: "growth")

    Account.current_transaction.after_commit do
      ProvisionAccountJob.perform_async(account.id)
    end

    account
  end
end
ActiveRecord::Transaction#after_commit attaches the block to the current transaction and carries it through parent transactions until the outermost commit. With no open transaction, current_transaction returns a null transaction whose callback runs immediately. Registering on a real transaction that has already been finalized raises ActiveRecord::ActiveRecordError instead.
There is a sharp edge here if your application uses multiple databases or abstract connection classes. Account.current_transaction asks Account's connection pool for its current transaction. The example is safe because both the transaction block and the lookup go through Account. If the open transaction belongs to a different pool, this lookup can see no transaction and run the block immediately, with no warning, recreating the race you meant to remove.
ActiveRecord.after_all_transactions_commit has broader semantics. It inspects the active connection pools and invokes its block only after every currently open, joinable transaction commits; a rollback suppresses the block.3 The word all is doing real work in that method name.
I prefer the workflow-level form when one use case, rather than every save of a model, creates the obligation. It leaves both decisions where a reviewer can see them: signup requires provisioning, and provisioning may begin only after signup commits. That is easier to reason about than a global hook whose callers must remember an invisible side effect.
Active Job does not defer every job by default
Applications using Active Job can ask the framework to perform the broader transaction registration:
class ApplicationJob < ActiveJob::Base
  self.enqueue_after_transaction_commit = true
end
The setting can also live on an individual job class. In Rails 8.1.3 it is a boolean and defaults to false. When enabled, Active Job delays the adapter call through ActiveRecord. after_all_transactions_commit; commit triggers the enqueue and rollback drops it.4
That behavior belongs to Active Job. A direct Sidekiq::Job.perform_async, Kafka producer, HTTP client, or custom publisher bypasses it. Seeing perform_later in one part of an application tells you nothing about a direct queue call hidden in a callback elsewhere.
Deferral also changes what a successful call means. perform_later can return a job instance while the database transaction remains open. Rails has accepted an instruction to enqueue later; the queue adapter has not accepted the job yet. If the adapter fails after commit, the original transaction has already succeeded and cannot report that failure by rolling back.5
A database-backed adapter can have different atomicity depending on where its queue tables live.6
Tests have a different outer transaction
There is an apparent contradiction waiting in many Rails test suites. With use_transactional_tests enabled, Rails wraps each test in a transaction that is rolled back during teardown. Nothing reaches a real outer commit, yet an after_commit assertion can still pass.
Rails makes the test wrapper non-joinable. When Active Record opens an inner transaction or savepoint, TransactionManager#begin_transaction computes run_commit_callbacks = !current_transaction.joinable?. The test wrapper is not joinable, so the inner commit callbacks run even though teardown later rolls the database state back.7 This is convenient for testing that a callback was registered and invoked. It is not evidence that another connection could see the row, that an adapter durably accepted a job, or that the handoff survives process death.
If one of those boundaries is the behavior you need to prove, write a focused test without the transactional wrapper and exercise the real adapter or integration boundary. Otherwise you can end up with a green callback spec around the exact race production is showing you.
The account now commits before the callback runs, and the job becomes visible in the right order. Fixing that race exposes a different gap.
The database commits, and then the process dies
1. COMMIT succeeds
2. after_commit beings
3. the job is pushed to the queue
after_commit guarantees that step 2 cannot precede step 1. It does not guarantee that step 3 happens.
The process can terminate after commit and before the callback runs. The queue adapter can reject the job. A callback can raise and prevent later commit callbacks from executing.8 The account remains in the database because rollback is no longer available.
The opening incident contained a job with no committed account. Moving the handoff to commit can expose the inverse incident: a committed account with no job.
For cache refreshes, search indexing, and ordinary notifications, monitoring plus an idempotent retry path may be enough. Provisioning a paid entitlement or charging an accepted order carries a stronger obligation. A durable outbox records the message intent in the same database transaction as the business change, and a separate publisher retries until it hands that message to the external system.
An outbox is beyond the callback lifecycle examined here, but its purpose separates the guarantees cleanly:
after_save     -> the SQL write succeeded on this connection
after_commit   -> the surrounding transaction committed
durable outbox -> the obligation to publish survived the process
I would not describe after_commit as reliable delivery. It is a timing guarantee, and a valuable one: downstream work starts after the database has accepted the state it depends on. When the business also requires the handoff itself to survive a crash, that obligation needs durable storage of its own.
Reconstruct the two timelines
A RecordNotFound inside a new job naturally sends a team toward queue retries. Before changing retry policy, find the outermost transaction and identify the exact enqueue path. Check whether the call passed through Active Job, whether enqueue_after_transaction_commit is enabled for that job class, whether the transaction and callback registration use the same pool, and whether the consumer reads from the primary database or a replica.
Rails already exposes the transaction boundary through ActiveSupport::Notifications. A small subscriber can put the actual outcome in your logs:
ActiveSupport::Notifications.subscribe("transaction.active_record") do |event|
  outcome = event.payload.fetch(:outcome) # :commit, :rollback, :restart, or :incomplete
  connection_object_id = event.payload.fetch(:connection).object_id

  Rails.logger.info \
    "event=transaction_finished outcome=#{outcome} " \
    "connection_object_id=#{connection_object_id}"
end
TransactionInstrumenter starts transaction.active_record when the database transaction materializes. It finishes the event with :commit or :rollback, but it can also report :restart when Rails restarts a transaction and :incomplete when a transaction is abandoned before completion.9 The connection object ID ties events together only inside one Ruby process. Add the request, job, or trace identifiers your application already carries when you need to correlate the request and worker across processes.
The important part is to log a boundary Rails actually emits, not an illustrative transaction_committed line that no application receives by default. A :restart tells you to follow the restarted transaction to its later outcome; and :incomplete event needs investigation before you classify the transaction as committed or rolled back.
If the worker starts before the :commit outcome, retrying has hidden a transaction-ordering bug. If the transaction reports :rollback, the job should never have been published. If commit came first and the job never appeared, the failure belongs to delivery after commit.
Those are different incidents because the guarantees are different. The record clock tells you that one write finished on one connection. The transaction clock tells you when the surrounding operation became visible. Neither clock can promise that a message reached another system; when that promise matters, record it durably and let delivery have its own retry loop.
Have you seen a retry make an after-commit rake look fixed? Reply or leave a comment with the symptom that finally exposed it.
Adapter commit followed by record and transaction callback execution lives in ActiveRecord::ConnectionAdapters::TransactionManager.
Parent propagation, immediate execution outside a transaction, and finalized-transaction behavior are implemented by ActiveRecord::Transaction; model access through current_transaction lives in ActiveRecord::Transactions.
ActiveRecord.after_all_transactions_commit collects open transactions across active connection pools and waits for all of them.
ActiveJob::EnqueueAfterTransactionCommit defers configured jobs through ActiveRecord.after_all_transactions_commit; ActiveJog::Enqueing defines the Rails 8.1.3 boolean with a default of false. Rails 7.2 used :default, :always, and :never with :never as the default. Rails 8.0 changed the job-class default to boolean false while accepting the symbols with deprecation warnings; the ActiveJob changelog records their removal, along with the deprecated application-wide setting in Rails 8.1.
Rails 8.1.3’s perform_later documentation still says enqueueing inside an Active Record transaction is implicitly deferred. The implementation in the same version defaults enqueue_after_transaction_commit to false, so that prose is stale unless the job opts in.
Solid Queue can share database atomicity when its queue tables and application writes use the same database transaction. Rails configures it on a separate database by default so application correctness does not quietly depend on that deployment detail. The Active Job guide recommends explicit commit deferral when jobs depend on committed application data.
ActiveRecord::TestFixtures pins each connection through pool.pin_connection!; ConnectionPool#pin_connection! opens the non-joinable wrapper transaction. TransactionManager#begin_transaction then enables commit callbacks on the inner transaction or savepoint.
The Active Record callback guide documents that commit-callback expectations roll back committed data and can stop later callbacks.
ActiveRecord::ConnectionAdapters::TransactionInstrumenter emits start_transaction.active_record, builds transaction.active_record, and adds :outcome when the transaction finishes.