
A support team suspends 37 accounts after a credential leak. The operation reports that all 27 rows changed, and a fresh query confirms that each account is now suspended.
The rest of the application tells a less tidy story. The audit screen has no suspension entries. updated_at still points to work performed hours earlier. Code that loaded the same accounts before the operation continues to see them as active.
Those are operational differences, not cosmetic ones. The missing audit row leaves the incident timeline incomplete, while an authorization check that reuses one of those loaded objects can still make a decision from active after the database has suspended the account.
Nothing raised, and the SQL did not roll back. The update succeeded while several behaviors the application associated with an account update never took part.
The model has an ordinary callback:
class Account < ApplicationRecord
  after_update :record_suspension,
    if: -> { saved_change_to_status?(to: "suspended") }

  private

  def record_suspension
    AuditEvent.create!(
      account: self,
      action: "account_suspended"
    )
  end
end
The suspension code uses a different persistence path:
accounts = Account.where(id: flagged_account_ids).load

Account.where(id: flagged_account_ids).update_all(status: :suspended)
# => 37
update_all did exactly what it promised. It built one type-cast SQL UPDATE, sent it to the database, and returned the affected-row count. It did not instantiate the 37 records, so there were no record callbacks to run, no automatic timestamp step, and no model instances for Rails to synchronize.1
When a callback appears not to have run, inspect the write method before debugging the callback body.
The method is often described as a faster version of update. Speed is a consequence of its smaller contract, which leaves several lifecycle stages out.
A persistence method chooses which parts of the record lifecycle participate.
That choice is more precise than “callbacks or no callbacks.” update_columns skips callbacks but changes its receiver. update_all has no receiver to change. insert_all skips model construction while still using model metadata and attribute types. delete changes its receiver but ignores the destroy lifecycle around associated records.
Two paths through Active Record
save coordinates several layers. Validations can stop the operation, callbacks surround it, dirty tracking selects attributes, timestamps join the write, SQL reaches the adapter, and a successful save moves pending changes into saved-change history.
The direct path starts below some of those layers:
application write intent
        |
        v
choose a persistence API
        |
        +-- lifecycle path
        |     validations where applicable
        |     callbacks
        |     timestamps and dirty-state transitions
        |     SQL
        |     receiver reflects the completed operation
        |
        +-- direct path
              model metadata and attribute types
              SQL
              affected rows or database result
              previously loaded objects stay as they were
update_columns shows why this is a lifecycle distinction: it uses ActiveRecord::Persistence and updates one receiver while bypassing most of the lifecycle. Relation-level update_all compiles SQL without visiting any affected record. ActiveRecord::InsertAll sits beneath both insert_all and upsert_all, using schema and type information without constructing model objects.23
A compact comparison makes those differences easier to see:
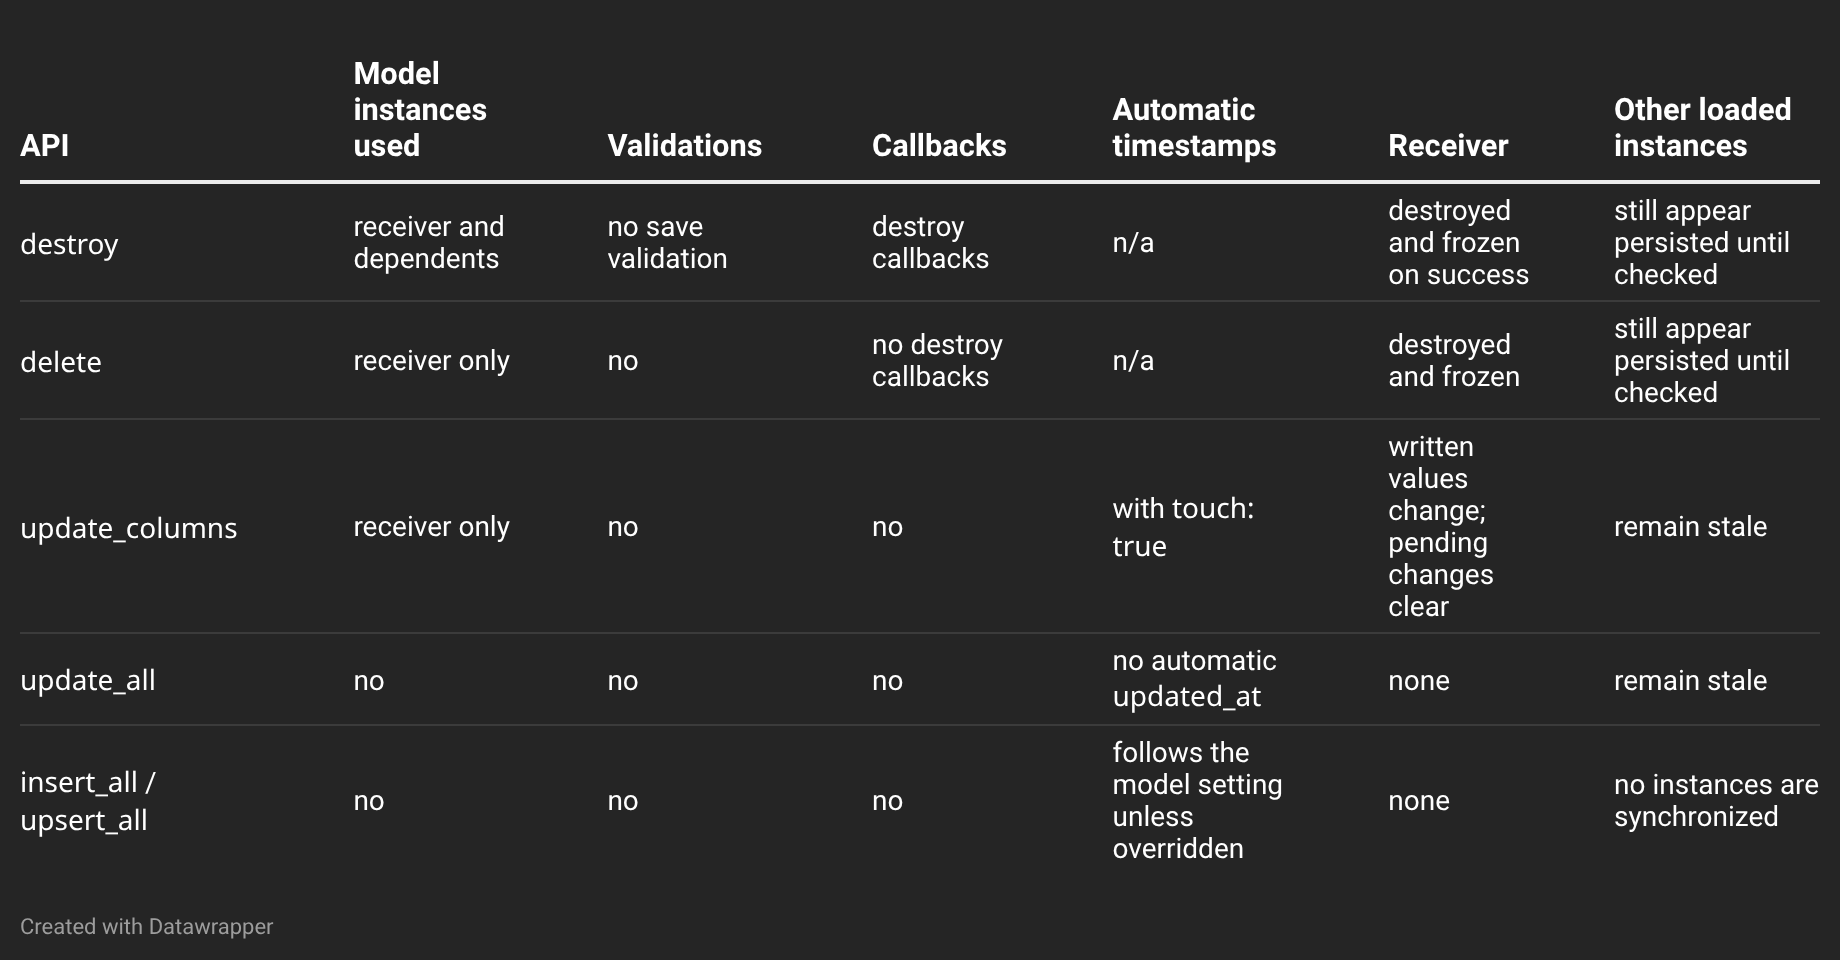
A single statement may be right for maintenance; one lifecycle per record may be required when each owns cleanup. Problems begin when code chooses the SQL shape and assumes the lifecycle comes along for free.
destroy and delete remove a row through different contracts
Two instance methods can issue a DELETE and leave their receivers looking similar afterward:
account.destroy

account.destroyed?
# => true

account.frozen?
# => true
and:
account.delete

account.destroyed?
# => true

account.frozen?
# => true
destroy runs the destroy callback chain and the association behavior attached to it. A before_destroy callback may abort. An association declared with dependent: :destroy can load and destroy its children. Only after that work does the receiver become destroyed and frozen.
delete sends a direct SQL deletion for the receiver’s row, then marks that receiver destroyed and freezes it. It does not run destroy callbacks or honor dependent association options.4
Suppose an account owns audit exports:
class Account < ApplicationRecord
  has_many :audit_exports, dependent: :destroy
end
account.destroy runs the dependent behavior. account.delete can leave the export rows pointing at an account that no longer exists. If the database has a foreign key that prevents that state, the direct delete raises instead. Either result is more precise than saying that one method “skips callbacks”: cleanup is absent, or the database refuses the incomplete deletion.
The relation-level pair makes the execution cost visible. destroy_all loads the matching records and calls destroy on each one. delete_all compiles one SQL DELETE, does not instantiate the records, and returns the affected-row count.
Account.where(dormant: true).destroy_all
# one destroy lifecycle per account

Account.where(dormant: true).delete_all
# one DELETE, no account destroy lifecycle
delete_all avoids allocating millions of Ruby objects and bypasses their cleanup decisions. Association and callback definitions decide whether that is acceptable.
update_columns takes the direct path through one object
update_columns occupies a useful middle position. It skips the save lifecycle, but it starts from a model instance:
account = Account.find(42)
same_row = Account.find(42)

account.status = :suspended

account.changes_to_save
# => { "status" => ["active", "suspended"] }
The call changes the named values on account:
account.update_columns(status: :suspended, touch: true)
# => true

account.status
# => "suspended"

account.changes_to_save
# => {}

account.saved_changes
# => {}
The example begins with a freshly loaded record, so saved_changes is empty. update_columns clears the pending change for every attribute it writes, but no save occurs, and Rails doesn't create new saved-change history for the operation. If the object already carried saved_changes from an earlier save, that order history remains.5
Rails 8.1 added touch: true to update_column and update_columns; the option is unavailable on Rails 8.0 and 7.x.6 It adds the model’s timestamp columns to this call. Without it, updated_at doesn't update automatically. Values still pass through Active Record’s normal type casting and serialization.
Only the receiver knows about the assigned values:
same_row.status
# => "active"

same_row.reload.status
# => "suspended"
One Ruby object followed the call. Another object representing the same database row did not. update_columns narrows the stale-object problem; it does not make model instances a synchronized view of the database.
update_all can create a delayed stale-object failure
The opening update_all has no receiver. The relation provides its table, predicates, and values, and Active Record compiles one statement:
loaded = Account.find(42)

Account.where(id: loaded.id).update_all(status: :suspended)
# => 1

loaded.status
# => "active"

loaded.reload.status
# => "suspended"
This is the snapshot boundary under a new cause. Another query or worker can make an object stale, but so can the direct path in the same process.
The method resets the relation after execution. It cannot search the process for every Account object that represents an affected row. Objects held by a controller, service, cache entry, or another thread retain the attribute they loaded earlier.
Optimistic locking makes that stale state produce a later and less obvious symptom. When the model has locking enabled, and the hash passed to update_all doesn't include its locking column, Rails increments lock_version.7
loaded = Account.find(42)

loaded.lock_version
# => 0

Account.where(id: loaded.id).update_all(status: :suspended)

Account.find(42).lock_version
# => 1
The next save through the old object carries version 0:
loaded.update!(email: "reviewed@example.com")
# raises ActiveRecord::StaleObjectError
StableObjectError prevents the old object from quietly overwriting the row. update_all adds this lock-version increment only for hash updates; raw SQL strings take a different path. When a loaded object later raises this exception or continues making decisions from old attributes, inspect earlier relation-level calls that used the direct path.
Next in The Persistence Boundary
A Rails validation can say a write is safe while another request is making the same decision.
Subscribe free for the next week’s chapter finale: the race only a database constraint can prevent.
SQL logs, the affected-row count, and a fresh query answer three different questions:
Did Rails issue the statement?
How many rows did the database change?
What state would a new object load now?
None of them tell you that an existing object was refreshed or a callback ran.
Bulk inserts use the model without running the model
A customer import provides the same boundary in the other direction. The normal account path canonicalizes email before validation:
class Account < ApplicationRecord
  before_validation :normalize_email

  private

  def normalize_email
    self.email = email.to_s.strip.downcase
  end
end
create! constructs an account, assigns the value, runs the callback, validates the result, and inserts the normalized email. A bulk import can take the direct path beneath that work:
Account.insert_all!([
  { email: " Ops@Example.com ", status: :active }
])

account = Account.find_by!(email: " Ops@Example.com ")

account.email
# => " Ops@Example.com "
The enum label is cast to its database value. The email string keeps its whitespace and case because no account ran normalize_email. If the application defines an attribute default in Ruby, that default also needs a model instance:
class Account < ApplicationRecord
  attribute :source, :string, default: "self_service"
end

Account.new.source
# => "self_service"
If the bulk row omits source and the database column has no default, the inserted row contains NULL. Database defaults still apply because the database owns them.
Calling these APIs “raw SQL” hides model metadata that still participates. ActiveRecord::InsertAll checks columns, raises ActiveRecord::UnknownAttributeError, casts and serializes values through model attribute types, and supplies timestamps according to record_timestamps. upsert_all can also update updated_at on its conflict-update path.8
The skipped work includes setters that require an instance, validation callbacks, model validations, ordinary create callbacks, and model-level attribute defaults.
The email example can produce two values the application considers equivalent while the database considers them distinct. A unique index protects equality as the database defines it; it cannot infer the canonicalization rule hidden in a skipped callback. Direct inserts make that division of authority visible sooner.
I would not repair that import by copying the callback body into a second code path. Move canonicalization into a shared method or value object used by both the model and the importer, then let each persistence path decide how much of the remaining lifecycle it needs. Otherwise, the two implementations can drift while appearing to enforce the same invariant.
Make the omitted work visible
Replacing every bulk write with a loop over save! would preserve more lifecycle and can impose a high cost. The opening operation has another valid repair: keep the one-statement update and express its required database effects as part of the bulk workflow.
now = Time.current

Account.transaction do
  affected = Account.where(id: flagged_account_ids).update_all(
    status: :suspended,
    updated_at: now
  )

  unless affected == flagged_account_ids.length
    raise "Expected to suspend every flagged account"
  end

  AuditEvent.insert_all!(
    flagged_account_ids.map do |account_id|
      {
        account_id:,
        action: "account_suspended",
        created_at: now,
        updated_at: now
      }
    end
  )
end
The code supplies one shared timestamp that update_all would omit, checks the affected-row count, and writes the audit records explicitly. insert_all! would normally derive timestamps from AuditEvent.record_timestamps; passing now keeps every audit row aligned with the account update.
The audit write also skips AuditEvent's record lifecycle. That is acceptable only if the model has no validation, callback, setter, or default behavior this operation requires. If it does, the bulk workflow must represent that work explicitly or use the lifecycle path. Both statements use the same database transaction, so an audit insert failure rolls back the account update.
This repair does not refresh objects loaded before the transaction. Its caller must reload them, stop using them, or return the identifier and let the next layer query fresh state. It also does not make an external queue or HTTP publish atomic with the database. That handoff still needs commit-aware timing and, when delivery must survive a crash, durable storage for the publishing obligation.
I would ask one question before approving any of these methods in application code:
Which behavior does this operation require from the record lifecycle?
For a deletion, the answer may include dependent cleanup. For an update, it may include normalization, timestamps, dirty-state history, an audit row, or current in-memory values. For a bulk import, model validations may be too expensive or inappropriate, but the database still needs to receive values that satisfy the application’s invariants.
Use the lifecycle path when coordinated behavior is required. Use the direct path when one SQL statement is the requirement and the skipped work is irrelevant or represented explicitly elsewhere.
Have you traced a missing callback, stale object, or absent audit row back to the persistence method? Reply or leave a comment with the method and the symptom.
ActiveRecord::Relation#update_all compiles one update, type-casts hash values, increments the optimistic-locking column when applicable, executes the statement, and resets the relation. It does not instantiate the affected records or update updated_at automatically.
Instance-level persistence methods live in ActiveRecord::Persistence; relation-level writes live in ActiveRecord::Relation.
ActiveRecord::InsertAll resolves model and relation metadata, verifies columns, casts and serializes values, supplies configured timestamps, and constructs the adapter-specific bulk statement without instantiating records.
ActiveRecord::Persistence#delete deletes the receiver’s row directly, then marks the receiver destroyed and freezes it. destroy invokes association and destroy-callback behavior before removing the row.
ActiveRecord::Persistence#update_columns applies attribute aliases, optionally adds touch timestamps, writes cast values into the receiver, clears each written attribute’s pending change, and performs the direct update without validations or callbacks.
The Active Record changelog for Rails 8.1.0 records adding touch: to update_column and update_columns. The option is absent from ActiveRecord::Persistence in Rails 7.1.3.4.
ActiveRecord::Relation#update_all compiles one update, type-casts hash values, increments the optimistic-locking column when applicable, executes the statement, and resets the relation. It does not instantiate the affected records or update updated_at automatically.
Rails 8.1.3 documents the timestamp, conflict, and return behavior of insert_all and upsert_all. Return columns depend on adapter support; PostgreSQL and SQLite support RETURNING, while MySQL does not.